What Are Guardrails in AI Agents and Why Do They Matter?

Key takeaways
- Guardrails are rules and checks that keep an AI agent safe, predictable and on task.
- Use layers: input, output, behavioral and contextual guardrails. If one fails, another still holds.
- Hard rules, like a payment limit, should be enforced outside the model so the agent cannot argue its way past them.
- Guardrails are not friction. They are what lets people trust an agent enough to use it.
What are guardrails in AI agents?
Guardrails are rules, constraints and safety mechanisms built into an AI agent platform to keep the agent's behavior predictable, controlled and trustworthy. They decide what the agent accepts, what it says and what it is allowed to do. That way the agent stays useful without leaking data, making unauthorized transactions or producing harmful responses.
In an agent harness, the software body around the AI model, guardrails work like reflexes: hard rules the agent cannot argue its way past.
Think of them like the lane markings, traffic signals, and speed limits on a highway. They don’t stop cars from driving fast or far, but they reduce the likelihood of accidents. Similarly, guardrails don’t prevent AI agents from being powerful, they ensure that power is used responsibly.
Guardrails can take multiple forms:
- Input Guardrails – controlling what the agent accepts as input. Example: rejecting personally identifiable information (PII) in a customer query.
- Output Guardrails – filtering or adjusting the agent’s responses. Example: preventing toxic or biased language.
- Behavioral Guardrails – defining what actions an agent is allowed to perform. Example: restricting access to financial APIs unless approved.
- Contextual Guardrails – limiting the agent’s operational scope. Example: only allowing data access from approved sources.
These layers combine to form a defense-in-depth model, ensuring that even if one layer fails, others will still enforce safety.
Why do AI agents need guardrails?
As AI agents grow more autonomous, the risks increase proportionally. Here are the major reasons guardrails are critical:
-
Prevent Harmful Outputs LLMs (large language models) are powerful but not infallible. Without guardrails, they can generate biased, toxic, or factually incorrect outputs. In sensitive industries like healthcare or finance, this is unacceptable.
-
Protect Sensitive Data Businesses must comply with strict data privacy regulations (GDPR, HIPAA, PCI-DSS, etc.). Guardrails prevent agents from accidentally storing, exposing, or mishandling sensitive information.
-
Maintain Business Alignment An autonomous agent may discover creative solutions, but not all of them align with a company’s brand, ethics, or legal obligations. Guardrails ensure that agents stay within approved workflows.
-
Enable User Trust For end-users and enterprises alike, trust is everything. Without strong guardrails, adoption of AI agents will stall because stakeholders will fear “black box” behaviors.
-
Regulatory Compliance Many industries are already under AI governance scrutiny. Guardrails help organizations demonstrate proactive compliance, reducing the risk of fines or regulatory action.
How do guardrails work in practice?
Guardrails can be implemented at multiple levels within an AI agent platform. Some common methods include:
-
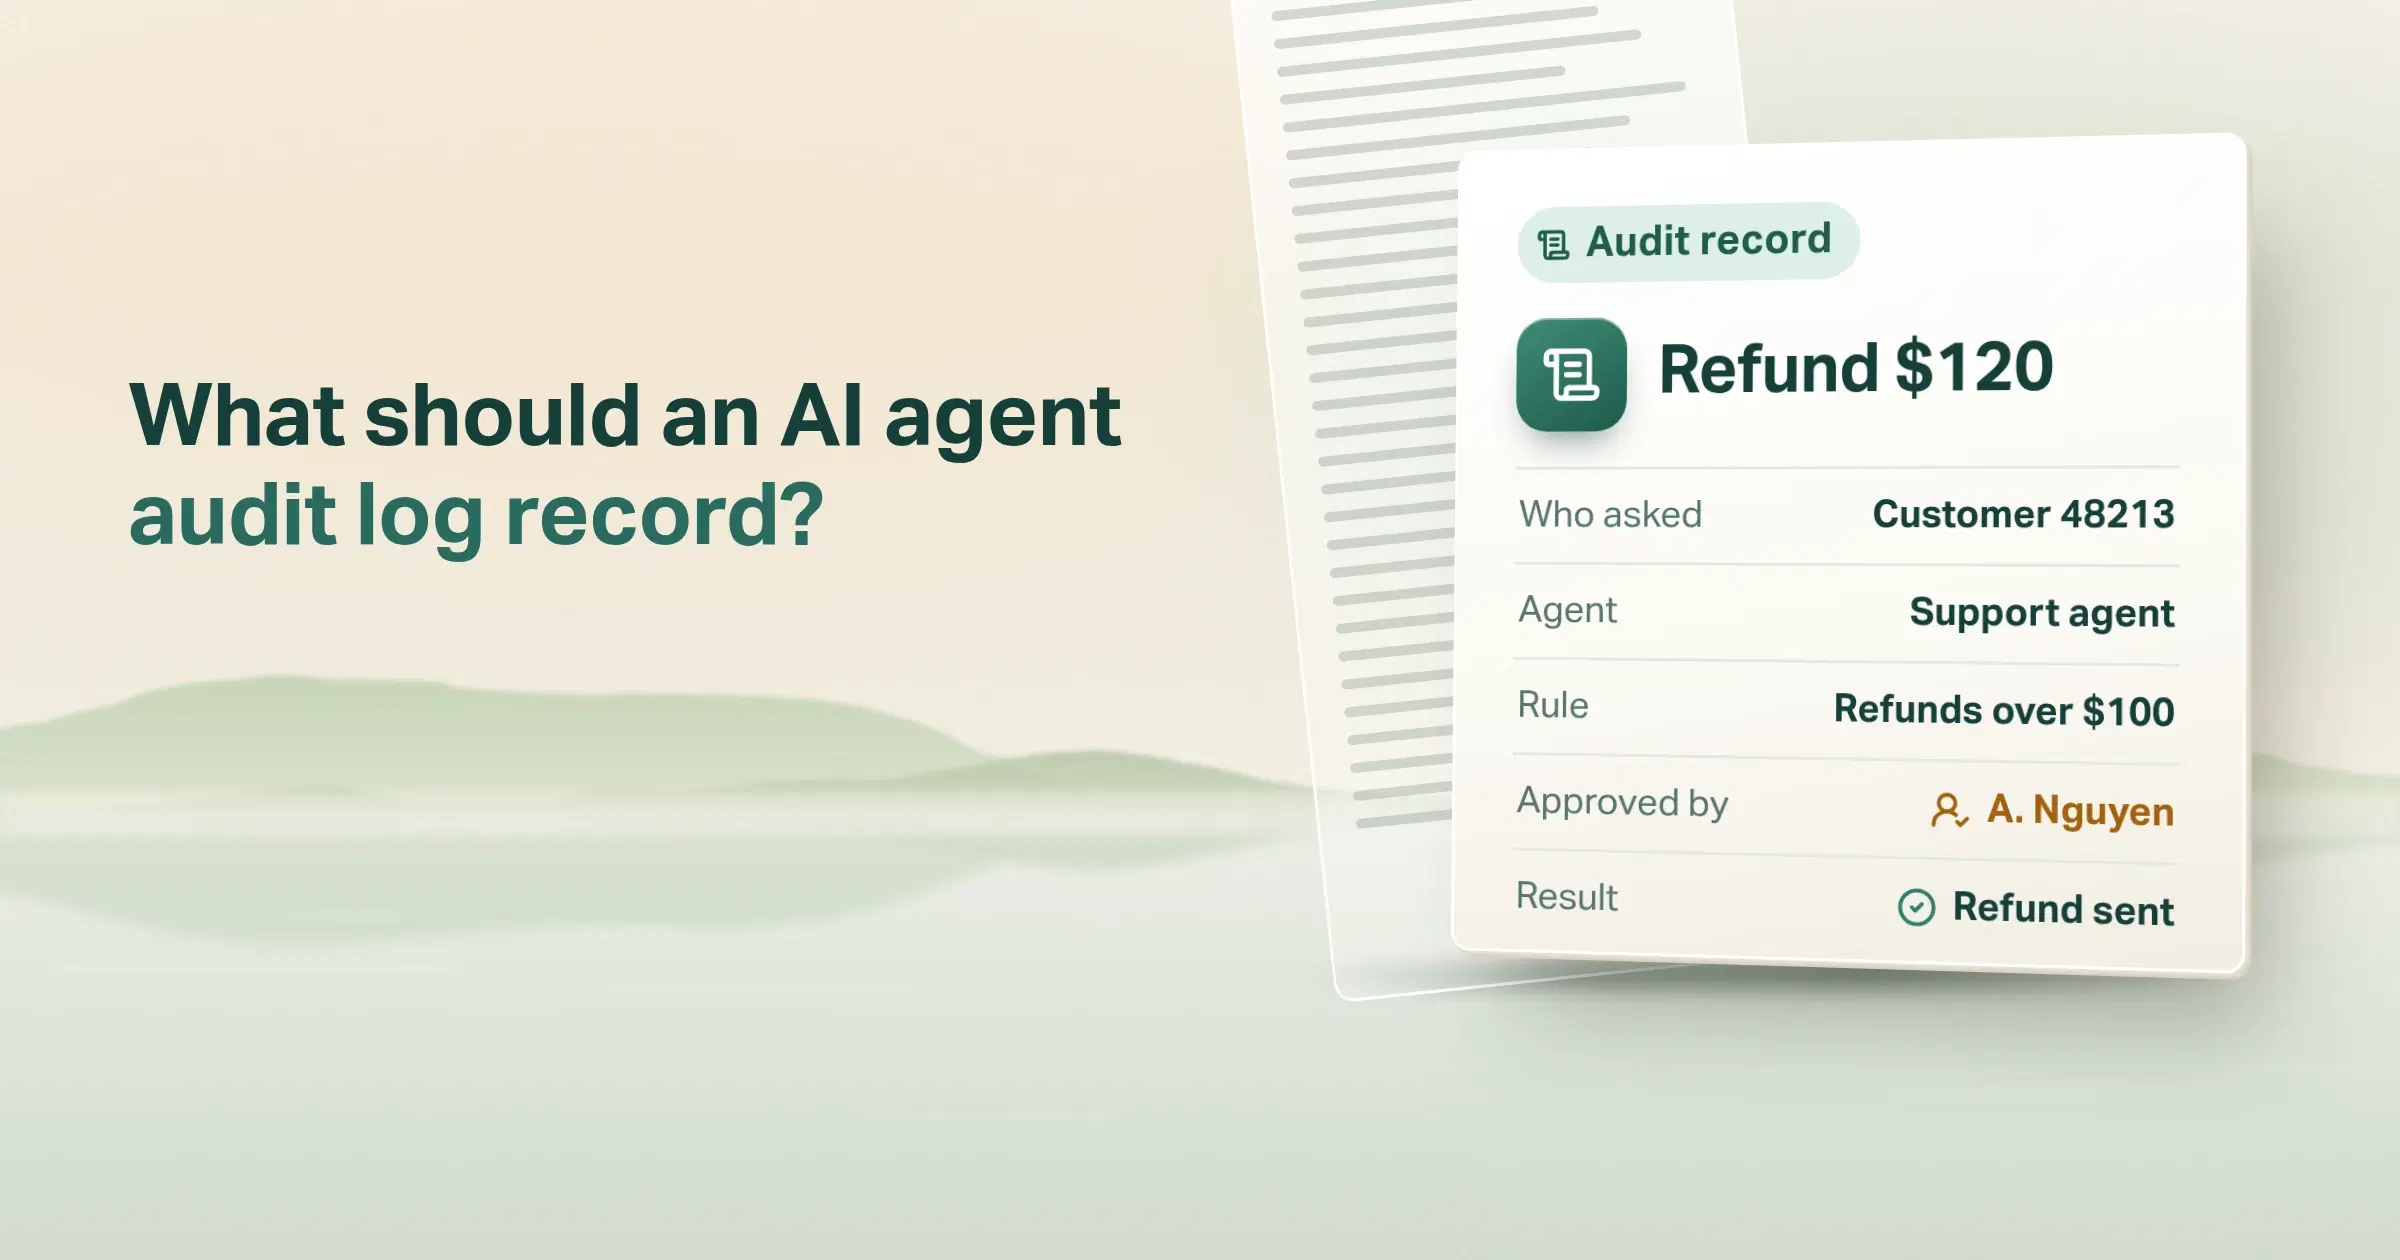
Rule-Based Filters Simple but effective. For example: blocking the inclusion of PII like social security numbers in inputs or outputs. Rules can also check the agent's own work. When we automated VIN extraction from Bills of Lading, a length and check digit rule decided which documents went straight through and which went to a person.
-
Moderation Models Using specialized AI systems to detect harmful, biased, or unsafe outputs before they reach users.
-
Role- and Permission-Based Controls Just like employees don’t all have the same system permissions, agents shouldn’t either. Guardrails enforce what an agent is allowed to do.
-
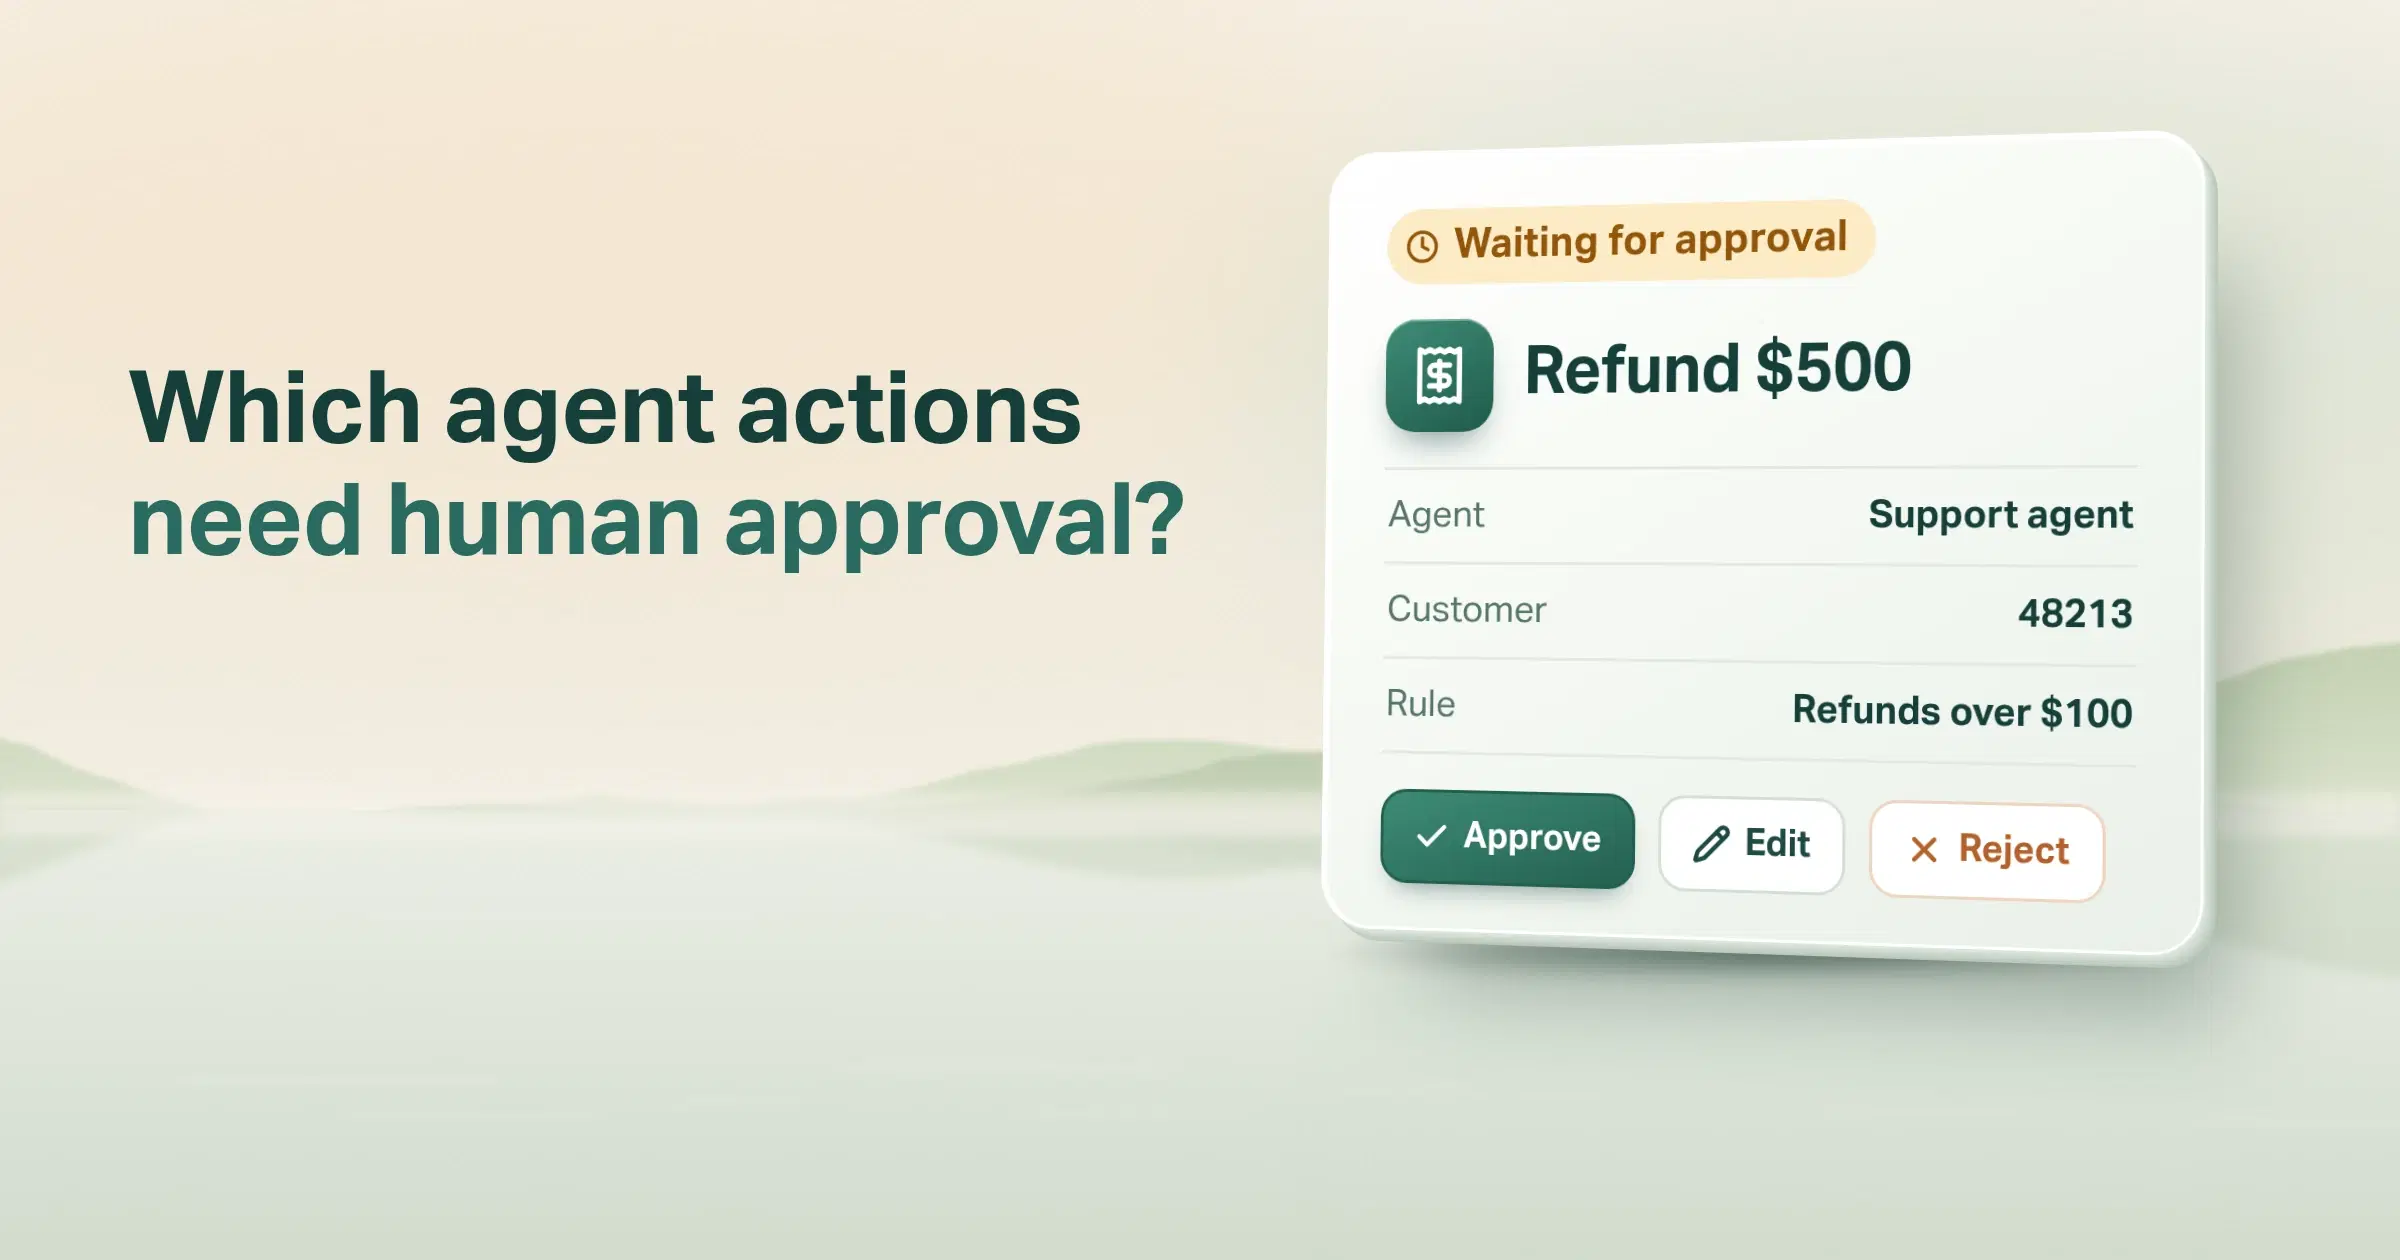
Human-in-the-Loop (HITL) Approvals For high-stakes tasks (like executing a financial transaction), the agent can request human approval before proceeding.
-
Sandboxing and Constrained Tool Access Agents often call APIs or external tools. Guardrails can sandbox these interactions, ensuring they only access approved tools or datasets.
-
Monitoring and Feedback Loops Guardrails aren’t “set and forget.” Continuous monitoring of agents in production and feedback allow them to adapt to evolving threats and edge cases.
Running all of this in production is what Safe AgentOps is for: the operating layer that adds evals, guardrails, audits, testing and monitoring to live agents.
What are examples of guardrails in AI agents?
- Finance → AI agents can draft reports, automate audits, or detect fraud. Guardrails ensure they don’t execute trades without authorization or expose sensitive financial data.
- Healthcare → Agents can assist doctors with summarizing records. Guardrails prevent them from offering unverified medical advice or mishandling patient data.
- Retail & E-commerce → Agents can personalize recommendations. Guardrails stop them from suggesting offensive content or misusing customer demographics.
- Customer Support → Agents can handle high volumes of queries. Guardrails ensure tone consistency, professionalism, and adherence to company policies.
Here is an accounts payable example. An agent processing a supplier invoice finds that it is 3% higher than the purchase order. It flags the difference instead of guessing. A hard rule says it can never pay more than the approved amount, so however convincing its reasoning, it cannot release the payment on its own. It sends the case to the finance manager with a clear summary, and the manager approves the corrected amount in one click. We walk through every step of this supplier invoice example in our agent harness guide.
The Business Case for Guardrails
Some leaders may ask: “Why should we spend resources on guardrails? Won’t they slow down the system?”
The truth is the opposite. Guardrails are not friction, they are trust enablers.
- They reduce legal risk by ensuring compliance with regulations.
- They protect brand reputation by avoiding embarrassing or harmful agent outputs.
- They accelerate adoption because customers and enterprises are more likely to trust a system that is visibly safe and controlled.
- They improve ROI by preventing costly failures, downtime, or legal actions.
Without guardrails, AI adoption at scale simply won’t happen.
The Future of Guardrails in AI Agents
Today, most guardrails are static rules or filters. But as AI agents evolve, guardrails themselves will need to become adaptive, context-aware, and self-learning.
Some emerging trends include:
- Dynamic Guardrails → adjusting safety thresholds depending on context (e.g., stricter for financial workflows than for internal brainstorming).
- AI-Driven Governance → systems that continuously monitor agent behavior and refine guardrails automatically.
- Cross-Agent Accountability → in multi-agent ecosystems, agents may check and balance each other.
- Explainable Guardrails → making guardrail decisions transparent so humans understand why an agent was blocked.
The future will not be about limiting AI agents, but about giving them the right frameworks to operate safely and responsibly at scale.
Conclusion
Guardrails are not an afterthought or a “nice to have.” They are the foundation of safe, trustworthy AI agent platforms. Without them, the risks of misuse, errors, or harm outweigh the benefits. With them, AI agents can transform industries with confidence.
As businesses explore AI adoption, the critical question is not just “What can the agent do?” but “What guardrails are in place to make sure it does it safely?”
For enterprises, startups, and developers alike, the message is clear: guardrails are the key to unlocking responsible autonomy in AI agents.
Frequently asked questions
- What is the difference between input and output guardrails?
- Input guardrails check what goes into the agent, such as blocking personal data or suspicious instructions in a user message. Output guardrails check what comes out before it reaches a user or another system, such as filtering toxic language or leaked data. Most production agents need both.
- What is the difference between rule-based and model-based guardrails?
- Rule-based guardrails are fixed checks, like blocking social security numbers, limiting payment amounts or allowing only approved tools. They are fast, predictable and easy to audit. Model-based guardrails use a moderation model to judge things rules cannot easily catch, like harmful or biased content, so they are more flexible but should be tested because they can be wrong.
- Do guardrails slow AI agents down?
- Simple rule-based checks add very little time. Moderation models and human approvals add more, so teams usually save them for higher-risk steps. In return, guardrails prevent costly failures and build the trust that real adoption needs.
- Can an AI agent bypass its guardrails?
- If a guardrail only lives in the prompt, a clever input or the agent's own reasoning can talk its way past it. Guardrails enforced in code outside the model, such as permissions and hard limits, do not depend on the model agreeing. That is why critical rules belong outside the LLM.
- Is human in the loop a type of guardrail?
- Yes. Human approval is a behavioral guardrail for high-stakes actions, such as executing a financial transaction. The agent prepares the work and a person gives the final yes before it goes ahead.
Share this article