LLM-Based Chunking for RAG: Is It Worth the Cost?
When an AI model should decide where your documents split, and when a simple rule does the job.
 Jeet Adeshara12 min read
Key takeaways
- LLM-based chunking has an AI model read a document and decide where each chunk starts and ends, so a chunk holds one complete idea, such as a whole clause or a table with its header.
- In a March 2026 study of 36 chunking methods, tiny fixed-size chunks of 100 characters were among the weakest, at 0.244. LLM boundary detection scored 0.415, and grouping whole paragraphs scored 0.459.
- The extra cost is paid once, when documents are indexed, not on every search. We use it on long PDFs where tables need their headers and clauses cross page breaks, and rarely on clean or short documents.
- Plan for model failures. Fall back to simple splitting where you safely can; otherwise mark the document as failed. Never index half a document without saying so.
- Test on your own documents before you switch: chunk 50 to 100 problem documents both ways and compare the answers to real questions.
A lawyer asks the firm's AI assistant when an employment contract can be ended. The assistant finds the right contract. It still answers badly: it quotes what happens after termination, but not the conditions that trigger it.
The search worked. The problem started earlier, when the contract was split into chunks (the short passages an AI assistant searches through). A fixed rule cut the clause in two, and the assistant only found one half. This look-up-then-answer setup is called RAG, short for retrieval-augmented generation.
This post explains LLM-based chunking, where an LLM (a large language model, the kind of AI behind ChatGPT) decides where to split each document. You'll see what the 2026 research says it's worth, how we run it in production, and when a simple rule is the better choice.
What is LLM-based chunking?
LLM-based chunking is a way to split documents for RAG where an AI model reads the text and decides where each chunk starts and ends. Each chunk holds one complete idea: a whole clause, a section with its heading, a table with its header. It costs more and runs slower than fixed-size splitting, and you pay that once, when documents are indexed.
Put simply:
A fixed rule splits by length. LLM-based chunking splits by meaning.
Why does chunking matter so much in RAG?
In RAG, the AI looks up passages in your own documents before it answers. It can only use the passages it finds. If a passage holds half an idea, the answer holds half an idea too.
That is why chunking quietly decides answer quality. A smarter search, such as hybrid search that also matches generated questions, helps find the right chunk. It can't repair a chunk that was cut in the wrong place.
Three common failures come from bad splits:
- A clause split in two. The conditions land in one chunk and the consequences in the next.
- A table without its header. The numbers arrive, but nothing says what the columns mean.
- A step without its explanation. The instruction is in one chunk and the reason for it in another.
What the model sees is its context, and good context engineering starts with complete passages.
Semantic chunking vs LLM-based chunking: what is the difference?
There are four common ways to split a document. They differ in who decides where the split goes.
| Method | Who decides the split | Cost to index | Good at | Weak at |
|---|---|---|---|---|
| Fixed-size chunking | A rule: every N characters or words | Lowest | Speed, huge volumes | Cuts sentences, clauses and tables |
| Paragraph or heading-based | The document's own structure | Low | Well-formatted documents | Messy text, scanned PDFs |
| Semantic chunking | Similarity scores between sentences | Medium | Text that drifts between topics | Tables, lists, legal structure |
| LLM-based chunking | An AI model reading the text | Highest | Long, structured documents | Cost and speed at scale |
Semantic chunking turns each sentence into numbers that capture its meaning, called embeddings. It splits where two neighbouring sentences stop being similar. It never reads the text the way a person would.
LLM-based chunking gives the text to a language model and asks it to find the natural breaks. It can also label each chunk, note its section and list the questions it answers. People also call this agentic chunking when an agent makes the choices, sometimes in several passes.
Which chunking method is best? What the 2026 benchmarks say
Two large studies this year give the most useful answer so far.
1. Tiny fixed-size chunks were among the weakest
In March 2026, researchers compared 36 chunking methods across six subject areas and five embedding models. They scored each method on how well the right passages landed in the top five search results (a measure called nDCG@5, where 1.0 is perfect).
| Method in the study | Score (nDCG@5) |
|---|---|
| Paragraph group chunking | 0.459 (best overall) |
| Dynamic token size chunking (chunk size adapts to the text) | 0.441 |
| LLM boundary detection chunking (a model picks the breaks) | 0.415 |
| Fixed-size chunks of 100 characters | 0.244 (one of the weakest) |
In this study, an AI model deciding the boundaries clearly beat very small fixed-size chunks. It did not beat grouping whole paragraphs, a much cheaper method that also respects the document's structure.
2. The cost lands at indexing time
The same study found the LLM-assisted methods "introduce massive preprocessing costs" in memory and time. It also notes that this overhead is "typically amortised as a one time indexing cost". In its tests, searches over LLM-made chunks still took under 4 milliseconds.
3. Expensive methods rarely win everywhere
In August 2026, a second study tested eight chunking strategies at scale. It found that expensive methods "rarely provide consistent gains over simpler chunking". The best choice depended on the embedding model, the documents, the corpus size and the measure used. An earlier study, published at NAACL 2025, reached a similar view on similarity-based semantic chunking. Both 2026 studies are preprints on arXiv (shared before peer review), so treat them as strong evidence, not the final word.
Very small fixed-size chunks are the weak option. LLM-based chunking is a tool for hard documents, not a rule for all of them.
How does LLM-based chunking work?
Most LLM-based chunkers we have seen follow the same four steps.
- The model reads the document. It sees the headings, sections, lists and tables, rather than a count of characters.
- It finds the natural breaks. A new heading, the end of a clause, or a change of subject marks a boundary.
- It builds chunks that stand alone. A section keeps its heading. A table keeps its header row.
- It adds labels that help search. These can be a section title, a content type, a short summary or questions the chunk answers.
Some teams go one step further. Anthropic's contextual retrieval adds a short explanation of where each chunk sits in the document before it is stored, so a chunk that says "the company" still makes sense alone.
How we chunk documents in Avesta AgentOS
Our knowledge layer, IngestIQ, is one of the four modules of Avesta AgentOS. It turns PDFs, web pages and connected files into chunks that our AI co-workers search. Page grouping is a setting for each run. It is on by default for files that arrive from a connected store, and when a document is reprocessed. With it on, here is how a long PDF is chunked, in plain steps.
- A long PDF arrives. The software marks every page, so the model always knows which page it is reading.
- The model groups pages by topic first. It splits only where a major heading starts or the subject changes. It is asked to keep each batch to 10 pages or fewer.
- The model chunks each batch. It keeps tables, lists and sections whole, and joins text that runs across a page break.
- Each chunk gets labels. These are its section title, a content type such as table, list or section, and 2 to 3 questions a user might ask.
- The software checks the page numbers. It maps each chunk back to the original pages, and rejects any page that isn't in the batch.
- The chunks are stored for search. The questions are searchable too, alongside the text.
Why we group pages before we chunk
A 300-page report is too long to chunk in one go. Cutting it every few pages brings back the original problem at a larger size: a chapter split across two batches. So the first pass asks only one question: where does each topic start and end? Each batch is then small enough for careful chunking.
What one chunk record holds
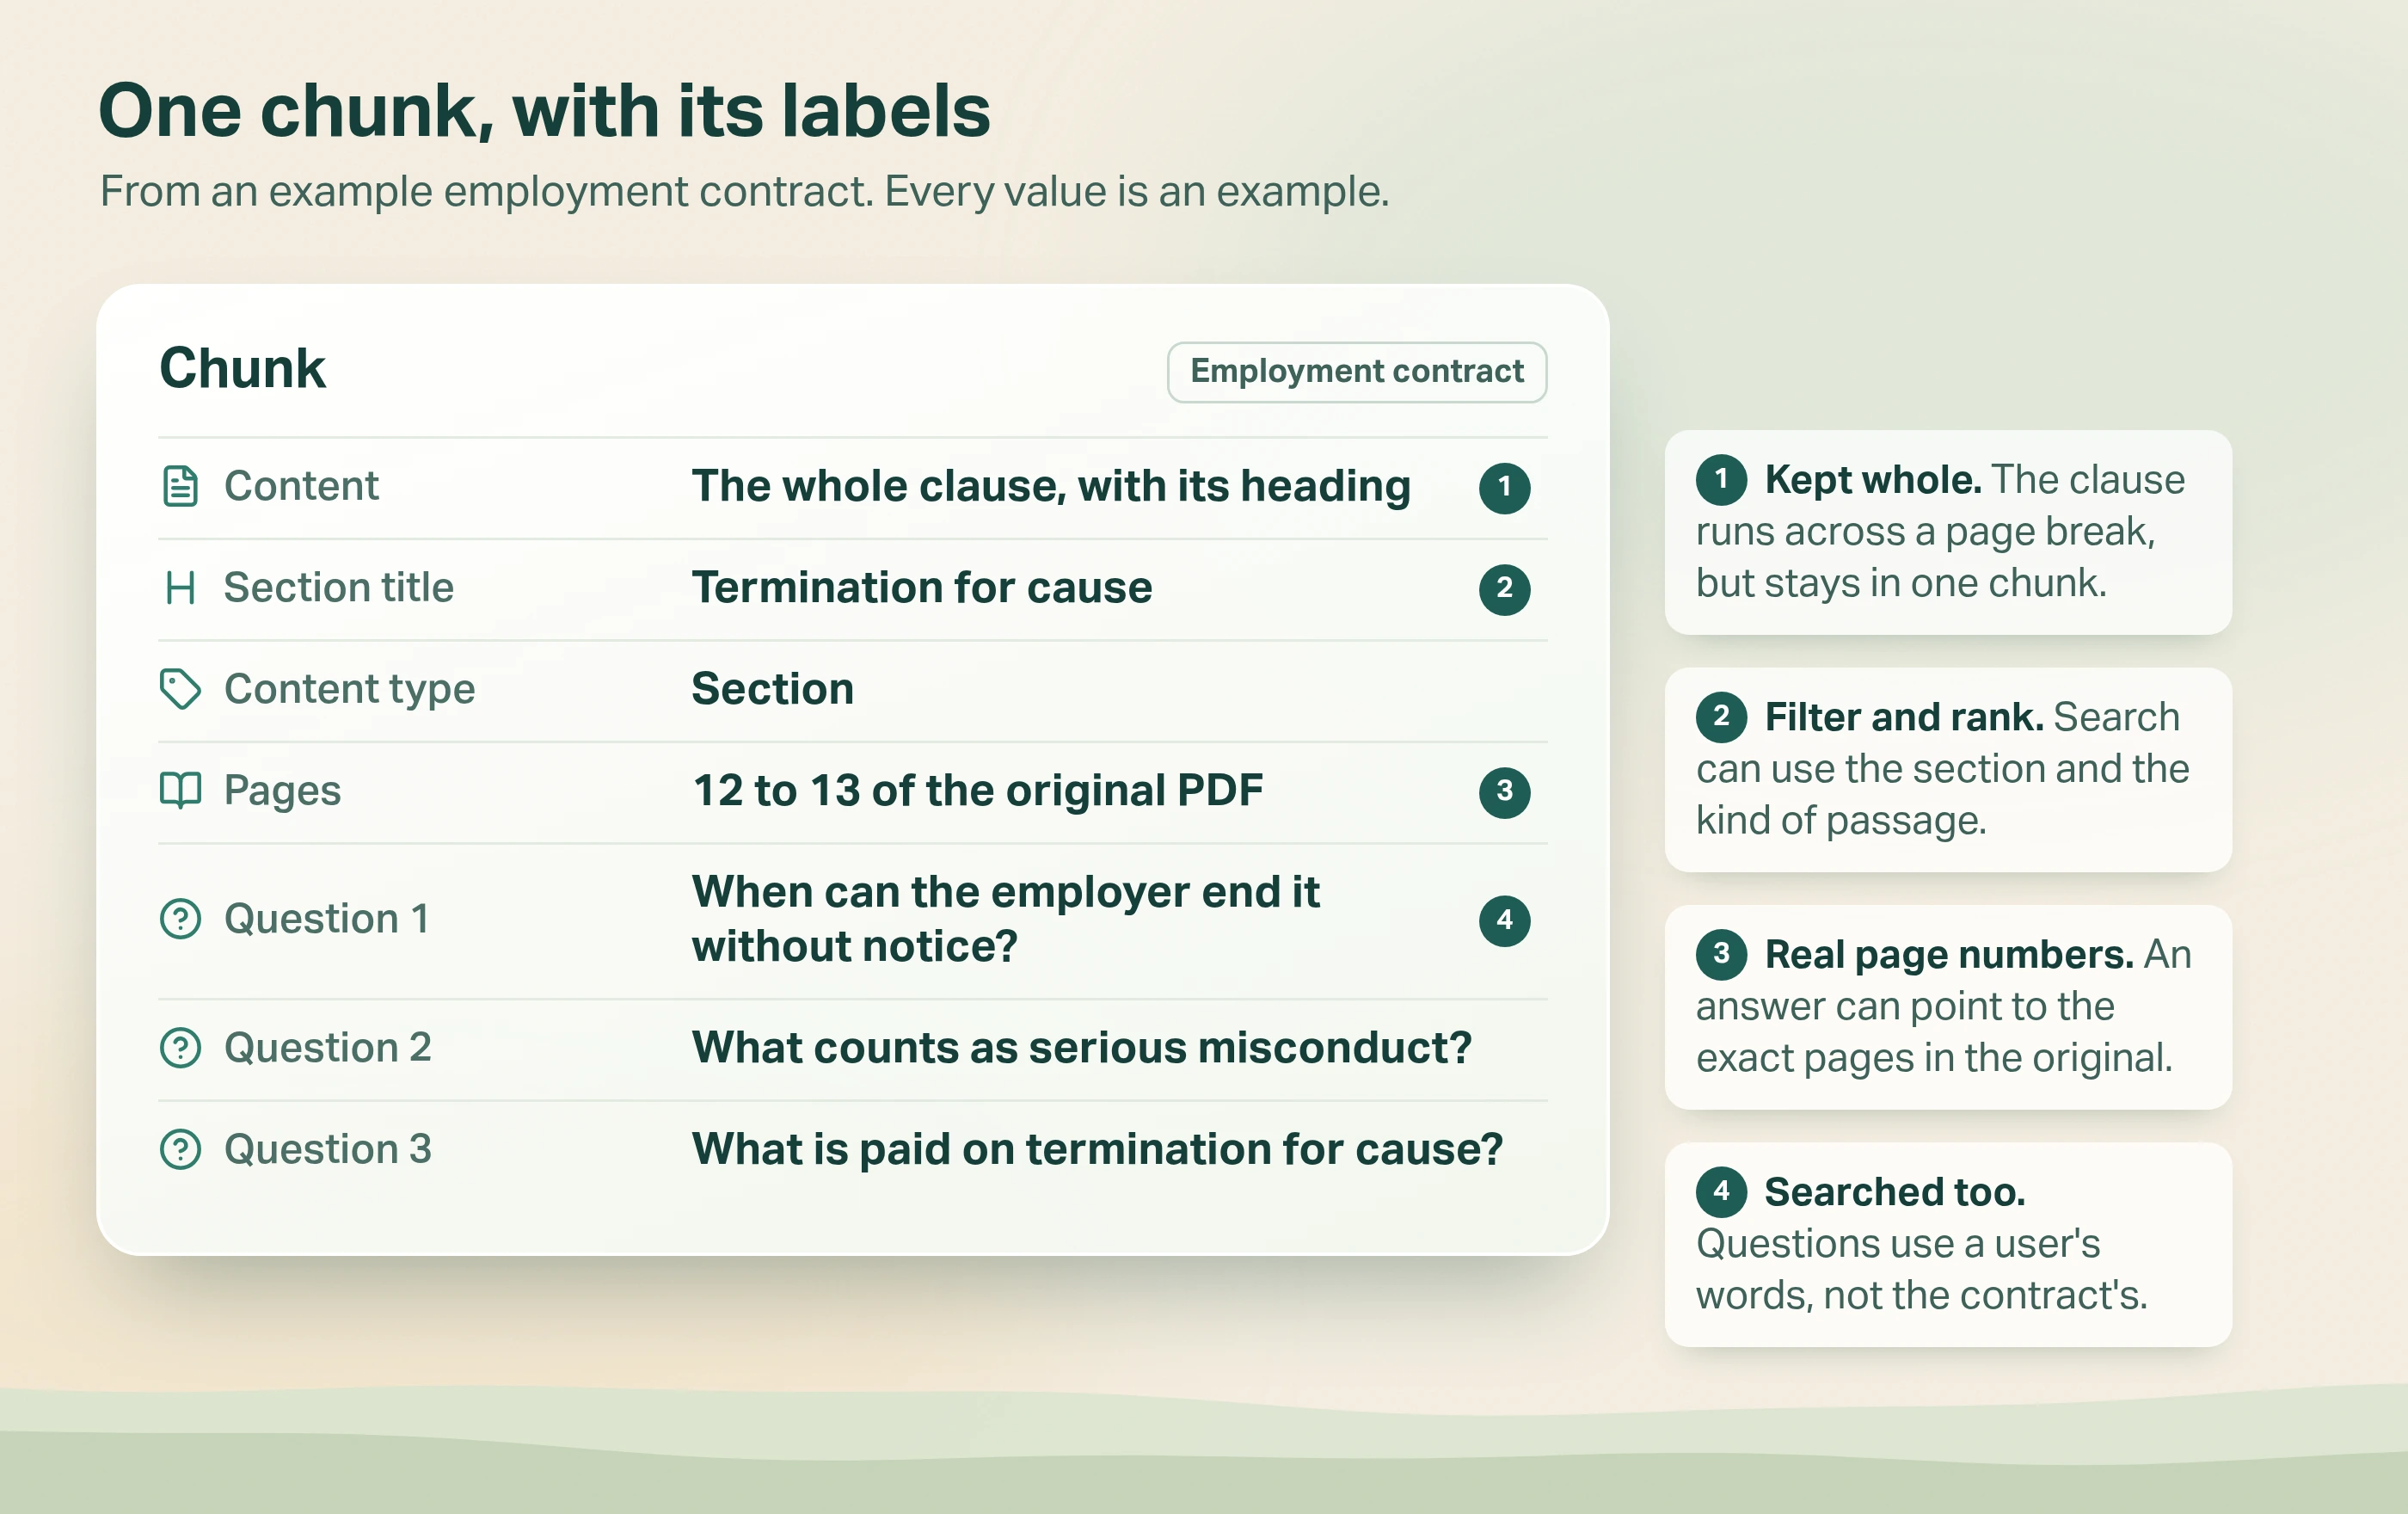
This is an example, not a real client document.
- The content is the whole clause, with its heading, even though it runs from page 12 to page 13.
- The section title and content type let search filter or rank by kind of passage.
- The pages point to the original PDF, so an answer can cite where it came from.
- The questions are written in the words a user would use, not the contract's wording. Our post on hybrid search for RAG explains how matching on those questions works.
What we do when the model fails
Models sometimes return a broken answer or time out. A model failure should never leave a document silently half-indexed. If page grouping fails, the software falls back to fixed batches of a few pages.
A batch that fails is tried up to 3 times. If it still fails, the document is marked as failed, so nobody mistakes it for a complete one. Token use and estimated cost are logged per document for the AI steps, including page grouping and embeddings, so we can see what chunking costs.
Rules per document type
The default rules already keep tables, lists and sections whole.
Teams can add their own instructions on top, per kind of document. The IngestIQ documentation gives a legal example: keep each clause complete and preserve section numbering. This is where a team's knowledge of its own documents enters the pipeline: the team writes the rule, and the model follows it.
When is LLM-based chunking worth the cost, and when isn't it?
The benchmarks above used one collection of long documents in six subject areas. In its legal documents, grouping whole paragraphs did best with every embedding model tested. The paper doesn't describe testing PDF layouts, tables or page breaks, so treat its results as a guide, not proof for your documents. Tables that need their headers and clauses that cross a page break are the cases we built IngestIQ's chunking for.
So treat this table as our starting rule from building IngestIQ, not a benchmark result. Then test it on your own documents.
| Your documents | Start with | Why |
|---|---|---|
| Legal documents as clean text | Paragraph or heading-based first | In the 2026 study, paragraph grouping did best on legal text |
| Contracts and reports as PDFs, with tables or clauses across page breaks | LLM-based chunking | Clauses and numbered sections must stay whole |
| Long PDF reports and manuals with tables | LLM-based chunking | Tables need their headers; topics span many pages |
| Wiki pages or Markdown docs with reliable headings | Heading-based chunking | The structure already marks the breaks |
| Product catalogues, short FAQs, support tickets | Fixed-size or one chunk per item | Each item is already short and self-contained |
| Millions of documents that change daily | Fixed-size or heading-based | Re-chunking every change with a model adds up |
When not to use LLM-based chunking
- Your documents are short and uniform. A one-paragraph FAQ answer is already a good chunk.
- Your documents change constantly. Every edit means another model call for that document.
- You have no way to measure the result. Without a test set you can't tell if the extra cost bought anything.
- The real problem is search, not splitting. If complete chunks still rank badly, fix ranking first.
How do you test LLM-based chunking on your own documents?
Start small. Pick 50 to 100 of the documents people complain about most. Chunk them both ways: your current method and LLM-based chunking.
Ask real questions. Use questions your users have actually asked, with answers someone has checked. For India Avenue's investor assistant, we tested against 50 real questions the client supplied and marked, and every change still runs against them (as of October 2026). That set tests the whole assistant, not chunking alone, which is the point: it shows whether answers got better.
Compare three things. Did the right passage come back? Was the answer complete? What did indexing cost per document? Our guide to what AI evaluation is covers how to build the test set and score it.
If you can't measure the difference on your own documents, you can't justify the cost.
The bottom line
LLM-based chunking lets an AI model split documents at natural breaks, so each chunk holds a complete idea. In 2026 research it clearly beat tiny fixed-size chunks, but not cheaper methods that follow the document's structure. Its cost lands once, at indexing time.
Use it where structure matters most: long PDFs where tables need their headers and clauses cross page breaks. Start cheaper on clean text and short documents. Plan for model failures, check the page numbers, and test on your own questions before you switch everything. Then make sure the right chunks rank first, with hybrid search for RAG.
Which of your documents would you trust an AI assistant to quote in full today?
Want an AI co-worker that answers from your own documents, with the source every time? See Avesta AgentOS, where IngestIQ handles chunking, search and connectors.
Get started: hello@avestalabs.ai
Frequently asked questions
- What is the difference between semantic chunking and LLM-based chunking?
- Semantic chunking turns each sentence into numbers that capture its meaning (embeddings) and splits where neighbouring sentences stop being similar. LLM-based chunking gives the text to a language model, which reads it and decides where complete ideas begin and end. The model can also label each chunk and add questions it answers. It costs more, because every document goes through the model.
- Which chunking method is best for RAG?
- No single method wins everywhere. A large 2026 study found the best method depended on the embedding model, the documents and the measure used. Grouping whole paragraphs did best overall in another 2026 study of 36 methods. Start with paragraph or heading-based splitting, and move to LLM-based chunking for long documents where tables, clauses and sections must stay whole.
- What is a good example of chunking?
- Take an employment contract. Fixed-size chunking might cut the termination clause in two, so one chunk holds the conditions and the next holds the consequences. Good chunking keeps the whole clause, with its heading, in one chunk. A question about when a contract can be ended then finds the complete answer in one place.
- What is chunking in machine learning?
- In RAG systems, chunking means splitting documents into short passages that can be stored, searched and handed to an AI model. The word is older than RAG. In language research, chunking meant grouping the words of a sentence into short phrases, such as noun phrases. A well-known 2000 research task defined it as dividing text into related, non-overlapping groups of words.
- What is agentic chunking?
- Agentic chunking usually means an AI agent decides how to split a document, sometimes in several passes, for example grouping related statements or choosing a strategy per document. The core idea is the same as LLM-based chunking: a model, not a character count, decides the boundaries. The names are used loosely, so check what a tool actually does.
- Is LLM-based chunking expensive?
- It costs more than fixed-size splitting, because every page passes through a language model. But you pay that once, when you index a document, not each time someone searches. Search speed is barely affected, because searching stored chunks doesn't call the model. Whether it is worth it depends on how many documents you have, how often they change and how much a half-answer costs you.
- What happens if LLM-based chunking fails on a document?
- Retry a few times first. Where a simple method can safely take over, such as fixed page batches instead of topic grouping, fall back to it. Where it can't, mark the document as failed and log why, so someone can look at it. Never store half a document as if it were complete. Also check the model's page numbers against the original document.
Share this article